 Trump administration offers mixed messages on limits to Ukraine’s Starshield access
 US Treasury proposes a rule to crack down on high-tech investments in China, other adversaries
 Calley Means, a key MAHA advocate, resigns as a top RFK Jr. adviser
 Spotify Tightens Family Plan Controls with QR Code Verification
 Use of Chief Minister C. Joseph Vijay’s deep fake videos to collect money: Rajasthan youth moves Madras High Court seeking bail
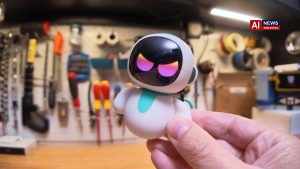
Users configure local AI models on personal devices
**
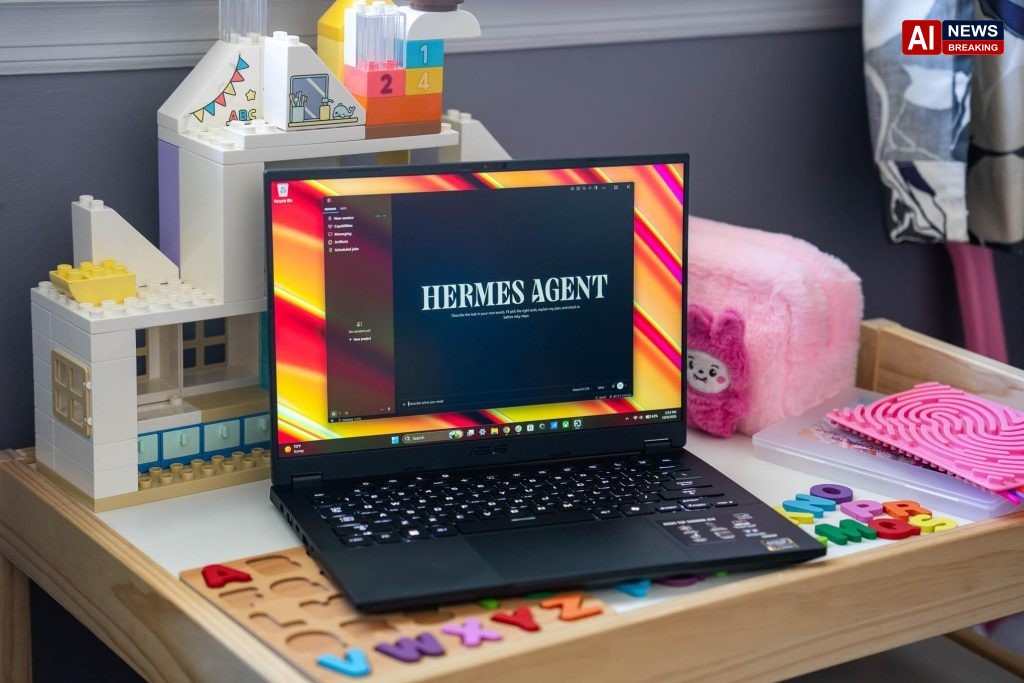
Users configure local AI models on personal devices - AI News Breaking
users configure local models:
The appeal of artificial‑intelligence tools has long rested on the promise of instant, cloud‑based assistance, yet the very convenience that makes them attractive also about privacy and control. Recent advances in hardware and software now allow many of the most capable language models to run on personal devices, sparking a wave of interest among hobbyists and professionals alike. For those who have hesitated to entrust their most sensitive data to remote servers, the prospect of a “local AI agent” offers a seemingly safer alternative..
The experience of setting up and using such an agent, however, is a mixture of excitement, technical frustration and occasional disappointment, a journey that reflects both the promise and the current limits of the technology.The first step in the process is choosing the right hardware. Modern consumer laptops equipped with high‑end graphics cards or Apple’s M‑series silicon can, in theory, host models that once required specialised server farms. Yet the price tag of a machine capable of running a 7‑billion‑parameter transformer comfortably can still be prohibitive for many users..
A typical setup might involve a laptop with 32 GB of RAM and a dedicated GPU with at least 8 GB of VRAM, or an Apple Mac Studio with its M2 Ultra chip. While these configurations are increasingly accessible, they remain far beyond the average consumer’s budget, prompting a question of whether the performance gains justify the expense.Once the hardware is in place, the software landscape presents its own set of challenges. Open‑source projects such as llama.cpp, GPT‑4‑All and Ollama have made it possible to download pre‑trained models and run them locally, but the process is far from plug‑and‑play..
Users must navigate command‑line interfaces, manage dependencies, and sometimes compile code from source. Documentation, while improving, can be uneven, and community forums often become the primary source of troubleshooting advice. For a newcomer, the learning curve can feel steep, especially when simple tasks like setting environment variables or allocating GPU memory result in cryptic error messages.The initial thrill of launching a local model often comes from the moment the system finally produces a coherent response..
Early interactions tend to be modest: the agent can answer factual questions, generate short paragraphs, or suggest code snippets. These capabilities demonstrate that a personal AI can function without sending data to external servers, preserving privacy in a way that cloud‑based services cannot guarantee. Moreover, the latency is typically lower, as the inference happens on‑device, eliminating the round‑trip time to distant data centres.However, the excitement is tempered by practical limitations..
Local models, even the larger open‑source variants, still lag behind the most recent cloud‑based offerings in terms of breadth of knowledge and linguistic nuance. Updates to the underlying data are infrequent, meaning that a model trained on a 2023 snapshot will not be aware of events or developments that occurred thereafter. Users quickly discover that while a local AI can draft an email or brainstorm ideas, it may stumble on more complex tasks that require up‑to‑date information or sophisticated reasoning.Another source of frustration lies in resource management..
Running a sizeable model consumes a significant portion of a machine’s memory and processing power, which can render the device sluggish for other tasks. Users often have to balance the AI’s performance against the need to browse the web, edit documents or stream media. Some solutions involve quantising the model to reduce its memory footprint, but this can degrade output quality, creating a trade‑off between speed, cost and accuracy that must be constantly negotiated.Security considerations, while less obvious, are also part of the equation..
Running code from third‑party repositories introduces the risk of malicious software, especially when models are downloaded from unverified sources. Although the open‑source community generally adheres to transparent development practices, the onus remains on the individual to verify checksums and ensure that the binaries have not been tampered with. This adds another layer of responsibility that cloud providers typically absorb through their own security infrastructures.Despite these hurdles, many users find the process rewarding..
The act of configuring a local AI fosters a deeper understanding of how these models work, demystifying a technology that often feels like a black box. It also encourages experimentation: developers can fine‑tune models on personal datasets, tailoring the agent’s behaviour to specific workflows, such as summarising legal documents or generating code in a preferred style. This level of customisation is rarely possible with hosted services that restrict model access.From a broader perspective, the rise of local AI aligns with a growing sentiment for data sovereignty..
As regulatory frameworks tighten around personal information, organisations and individuals alike are seeking ways to retain control over their digital footprints. The ability to run a capable language model on a personal device offers a tangible path forward, even if it currently appeals mainly to technically adept users willing to invest time and resources.The journey of adopting a local AI agent thus oscillates between enthusiasm and exasperation. Early adopters report a mix of “aha” moments—when the model produces a surprisingly apt response—and moments of irritation, such as crashes caused by insufficient VRAM or cryptic library conflicts..
Over time, many find that the experience settles into a rhythm: the AI becomes a useful, if imperfect, assistant that can be called upon without exposing data to external servers, while the user becomes more adept at navigating the technical intricacies involved.In the final analysis, the decision to invest in local AI hinges on individual priorities. For those whose primary concern is privacy, and who are comfortable handling the technical setup, the benefits may outweigh the costs. For users seeking the latest performance and up‑to‑date knowledge without the hassle of configuration, cloud services remain the more convenient choice..
As hardware continues to evolve and open‑source models improve, the gap between local and remote AI is likely to narrow, potentially reshaping how everyday users interact with intelligent software. Until then, the path remains one of both promise and patience, inviting a new class of users to explore what it means to have artificial intelligence truly at hand..
Updated: October 11, 2026
Local AI promises data sovereignty but currently entrenches a tech‑elitist divide, turning privacy into a premium feature for those who can afford the hardware and the expertise. As open‑source models mature, the tension between convenience and control will force mainstream providers either to decentralize their services or risk ceding the privacy‑conscious market to a niche of DIY adopters.